An agent fails partway through a run. The session ends in a dead end, the branch is stranded, and the next run starts from zero. Later, a different session hits the same broken test and solves it from scratch, because nothing carried the first fix forward.
These are all common scenarios in engineering teams that rely on AI testing. They impact shipping speed and bring manual work back into a process that promised automation.
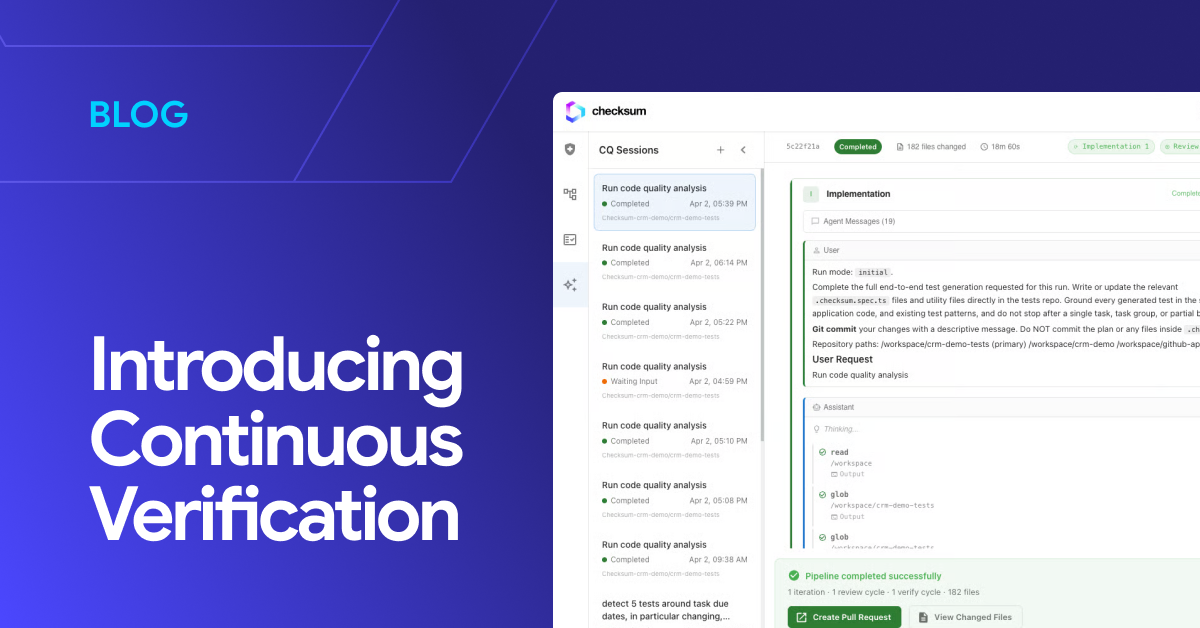
The foundation of Checksum’s continuous quality platform is that every fix an agent produces is verified against a real test result. Now, Checksum's Continuous Quality Loop makes verification part of the cycle the agent is already in with:
- Sessions that survive a failure and resume where they left off
- Memory that carries every proven fix into the next session
Key takeaways
- Proven fixes are reused only where they fit. Checksum saves a fix to memory once a real test result proves it, and pulls it into a future session only when the new failure matches what the previous one was about. Fixes your team has explicitly flagged always surface.
- Teams control how much reasoning goes into a fix. Checksum's auto-recovery has four speed settings. The most thorough reasons step-by-step through complex failures, two faster settings trade some depth for speed on routine repairs, and the fastest attempts a single high-confidence correction, so teams can match recovery effort to the failure.
- A fix from memory still has to pass a fresh test run. When a second test hits a failure Checksum has already solved, it starts from the stored fix instead of working out what changed from scratch. It then confirms the result with its own independent test run before the fix counts.
Memory: every proven fix carries forward
Once a fix is proven against a real test result, Checksum commits it to memory. Memory items also carry optional repository, environment, workflow, and phase fields for finer targeting. If and when a future session hits the same pattern, it starts from what is already solved instead of solving it again, so your team doesn’t have to fix the same broken test twice.
What that means in practice is that Checksum only pulls a stored fix into a new session when the failure it's looking at resembles the one that the fix solved. It looks at what the failure and the fix are really about, not just a keyword match. The one exception is a correction your own team has explicitly flagged. It shouldn't get filtered out just because a new failure happens to be worded differently, so it will always surface.
Auto Recovery speed settings
Within a single test run, auto-recovery corrects course in seconds. Four tunable speed settings now let teams choose how much reasoning goes into a fix: the most thorough setting reasons through a failure step-by-step for the trickiest cases, two faster settings trade some of that depth for speed on routine repairs, and the fastest is built for a single, high-confidence corrective action. It makes one attempt to resolve on the spot or is handed off.
The Continuous Quality Loop at work
For fixes that are verified and merged automatically, the loop now closes four times faster than before. Here’s what that looks like across two sessions.
First session: A test fails because a confirmation modal now appears partway through checkout—a new step the test doesn't know about. The agent classifies it as a test issue rather than an app bug and updates the test to acknowledge the modal before moving on. The fix is confirmed by a fresh test run, not the agent's own report. Because it captures something reusable about how checkout now works, not a one-off edit to a single test, it's stored in memory.
Second session: A different test that also goes through checkout fails at the same point. Instead of working out what changed from scratch, the session starts with the stored fix, applies it, and verifies the result with its own fresh test run. Verification never gets skipped because memory has a prior answer.
Holding every agent fix to a real test result has a measurable impact on the volume of failures that teams encounter. In the 2026 State of Code Verification, test suites with continuous verification saw an 82% reduction in failure rates compared to teams without it.
Verification built into the loop
Loop engineering happens when verification is part of the cycle the agent is already in, not a separate step someone has to remember. As I explained at the product launch, most agent output still comes with a claim attached to it instead of evidence. We built the Continuous Quality Loop so the claim has to survive contact with the actual test run, not just the agent's account of it.
Watch the Continuous Quality Loop in action below, or speak to us about adding continuous verification capabilities to your team’s test suite.
FAQs
What is Checksum's Continuous Quality Loop?
The Continuous Quality Loop is how Checksum builds verification into the cycle an AI testing agent is already running. Every fix the agent produces must pass a fresh test run, not just the agent's own report. Fixes that capture something reusable are saved to memory, so later sessions start from the known solution instead of solving the same problem again.
How does Checksum decide when to reuse a stored fix?
Checksum compares each new failure with the fixes in memory and pulls one into the session only when the new failure resembles the one that fix solved. It matches on what the failure and fix are about, not keywords. Stored fixes can also be targeted by repository, environment, workflow, or phase. Corrections your team has explicitly flagged always surface, even when a new failure is worded differently.
Does reusing a fix from memory skip verification?
No. A fix pulled from memory still has to pass its own fresh, independent test run before it counts, not just the agent's report that it worked. Each additional passing run attaches more evidence to the stored fix, which is how it moves from a provisional match to a trusted one.